Rubin Wei
I’m a second-year Ph.D student in Computer Science at the School of Artificial Intelligence, Shanghai Jiao Tong University (SJTU), advised by Prof. Zhouhan Lin in the Language Understanding and Machine Intelligence Algorithms (LUMIA) Group. Previously, I received my B.E. in Information Security from Wuhan University.
My research centers on memory, pretraining, and architectures for large language models and agents.
Training memory modules to internalize and retain knowledge from large-scale training corpora.
Designing memory-augmented models and pretraining paradigms for efficient and adaptive knowledge access.
Advancing pretraining methods and model architectures for foundation models.
News
I am currently seeking research internship opportunities with foundation model teams, especially in pretraining.
Mixture-of-Memories released on arXiv.
Deep Fusion Memory released on arXiv.
HABIT-Bench released on arXiv.
NCP-ArchPreview technical report released.
Intern-S2-Preview technical report released.
Memory Decoder at Scale released.
MemSFT released.
MLP Memory accepted to ICLR 2026.
Memory Decoder accepted to NeurIPS 2025.
Selected Publications
All publications on Google Scholar.
2026
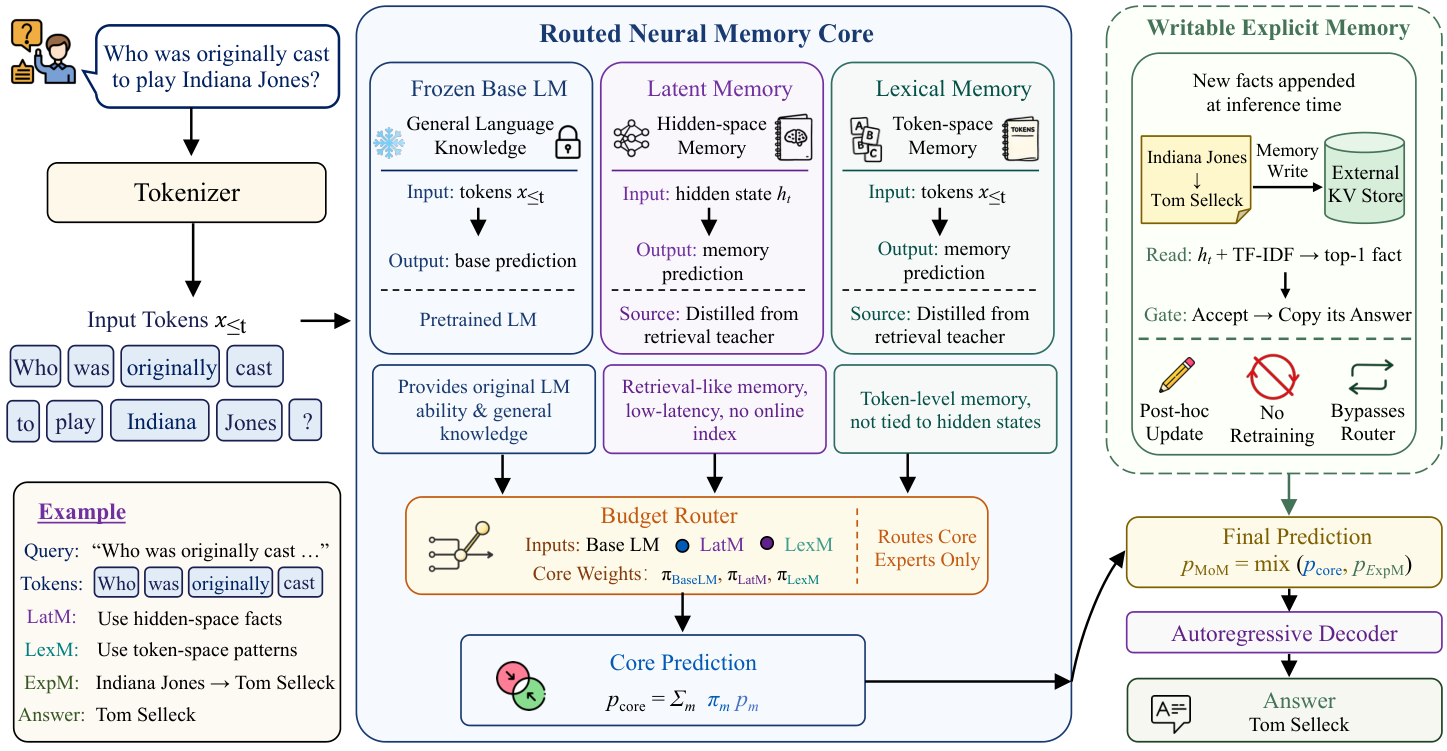
Mixture-of-Memories: Low-Overhead Language Modeling with Modular Knowledge Injection
arXiv preprint, 2026
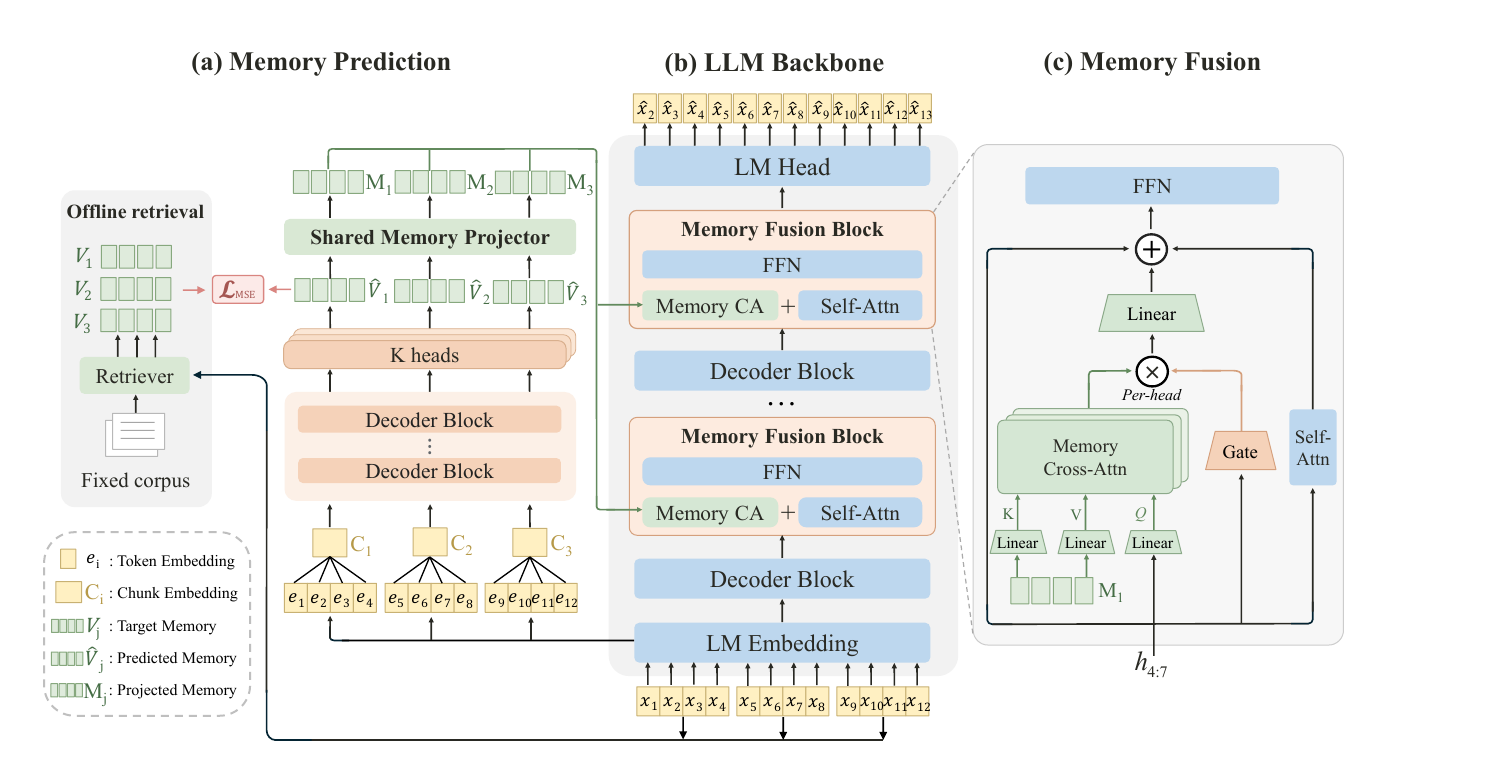
Deep Fusion Memory: A Chunk-Level Parametric Memory for Large Language Models
arXiv preprint, 2026
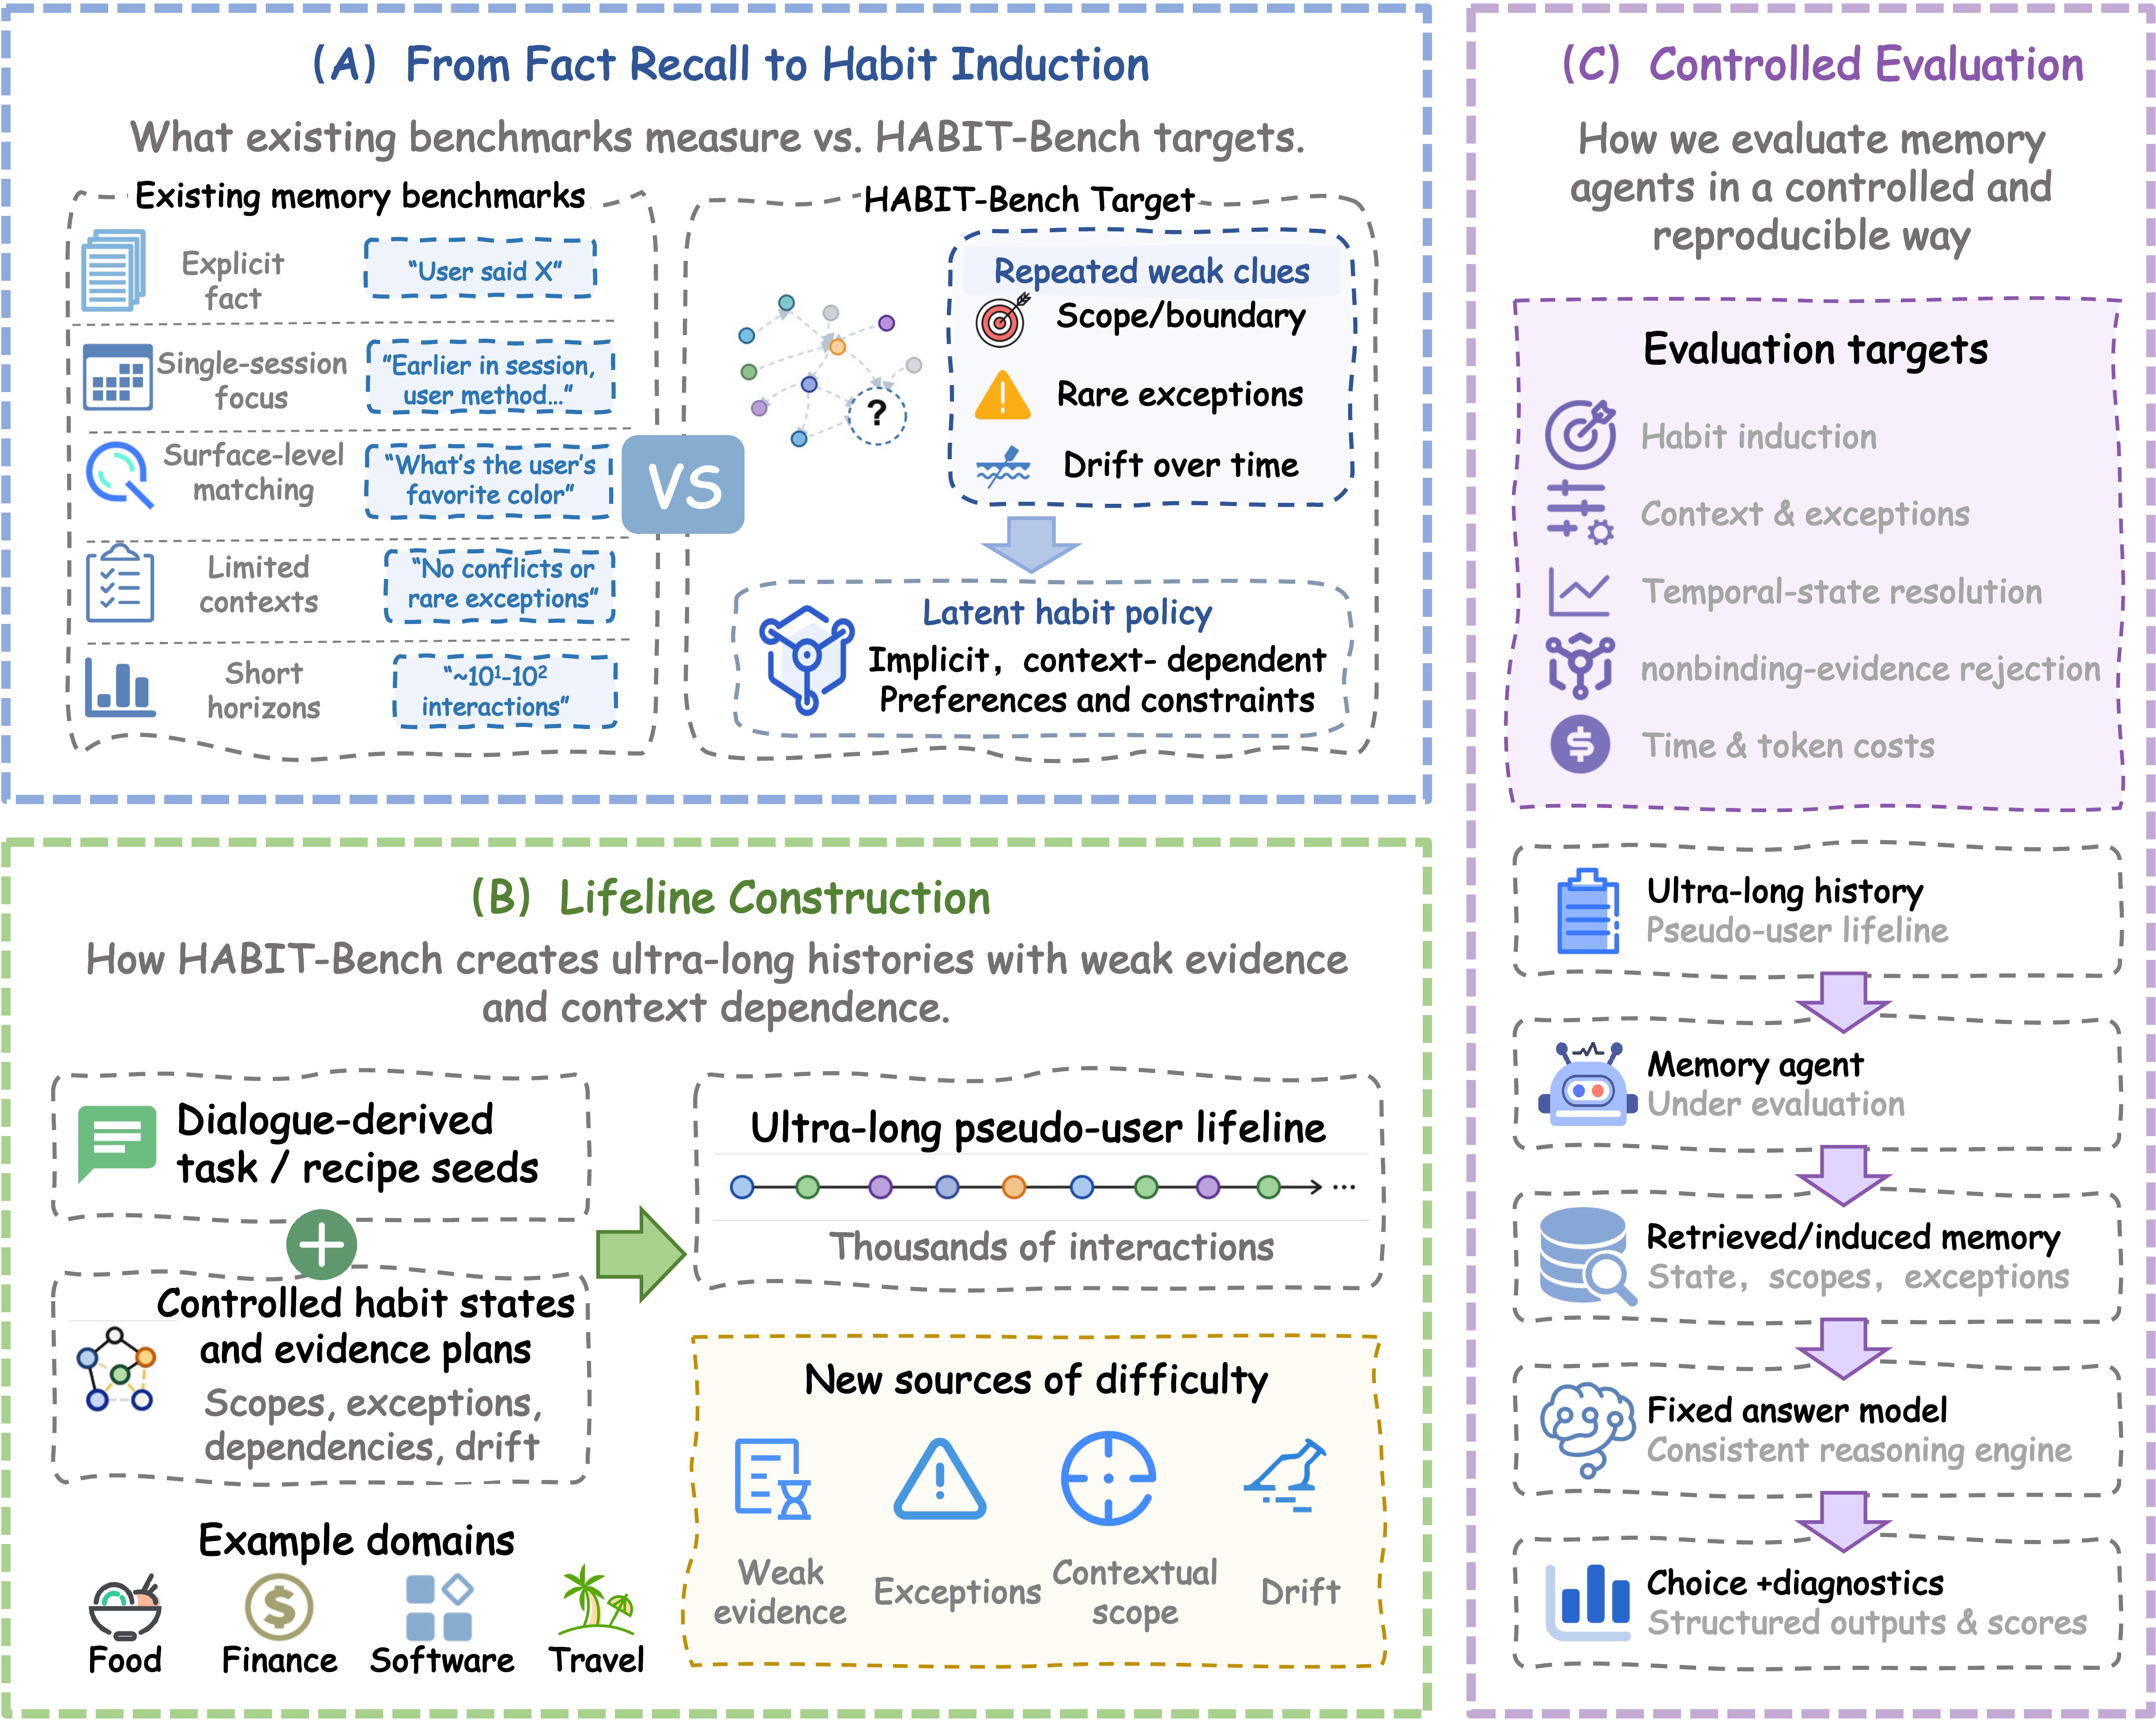
HABIT-Bench: Evaluating Habit Induction from Longitudinal Weak Evidence in Agent Memory
arXiv preprint, 2026
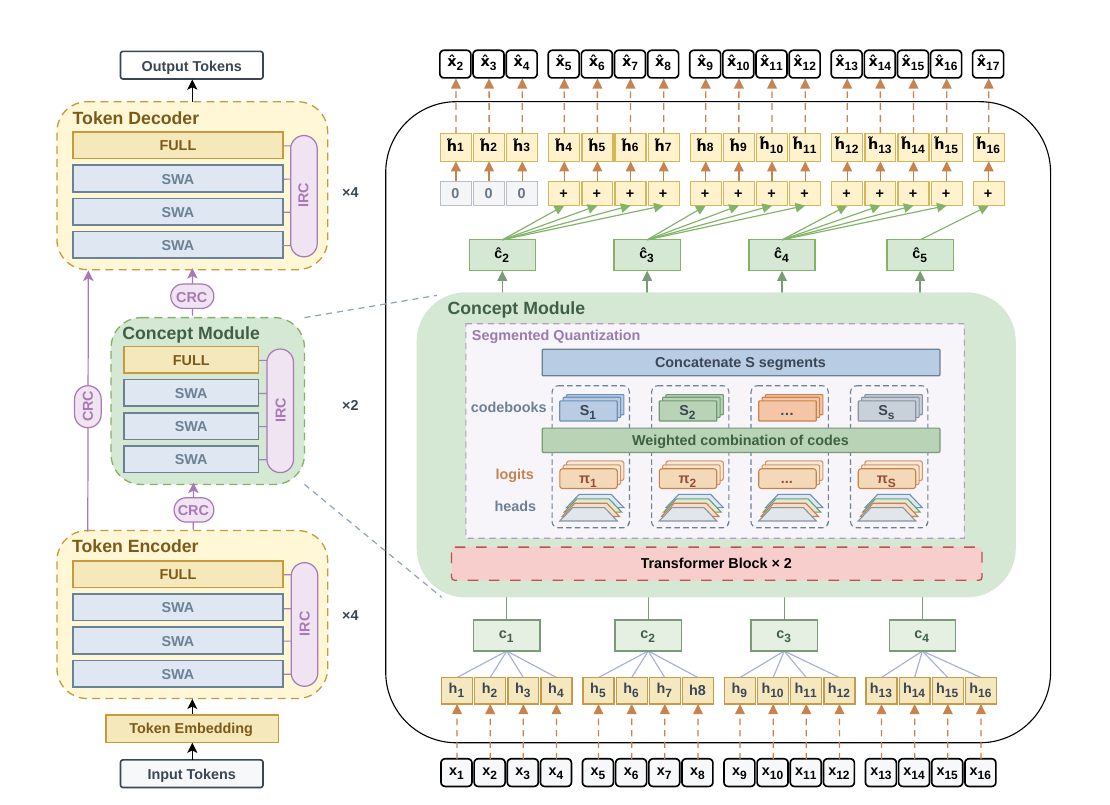
NCP-ArchPreview Technical Report: Moving towards Latent Space Language Models through Next Concept Prediction
Technical Report, 2026


Memory Decoder at Scale: A Pretrained, Parametric Long-Term Memory
Preprint, 2026

MemSFT: Mitigating Alignment Tax with an External Parametric Memory
Preprint, 2026
* Equal Contribution

MLP Memory: A Retriever-Pretrained Memory for Large Language Models
International Conference on Learning Representations (ICLR), 2026
* Equal Contribution
2025

Memory Decoder: A Pretrained, Plug-and-Play Memory for Large Language Models
Annual Conference on Neural Information Processing Systems (NeurIPS), 2025
* Equal Contribution